Data that cannot leave
Legal, medical, financial or simply confidential: teams that want AI but cannot ship documents to a public API.
0
AI integration services
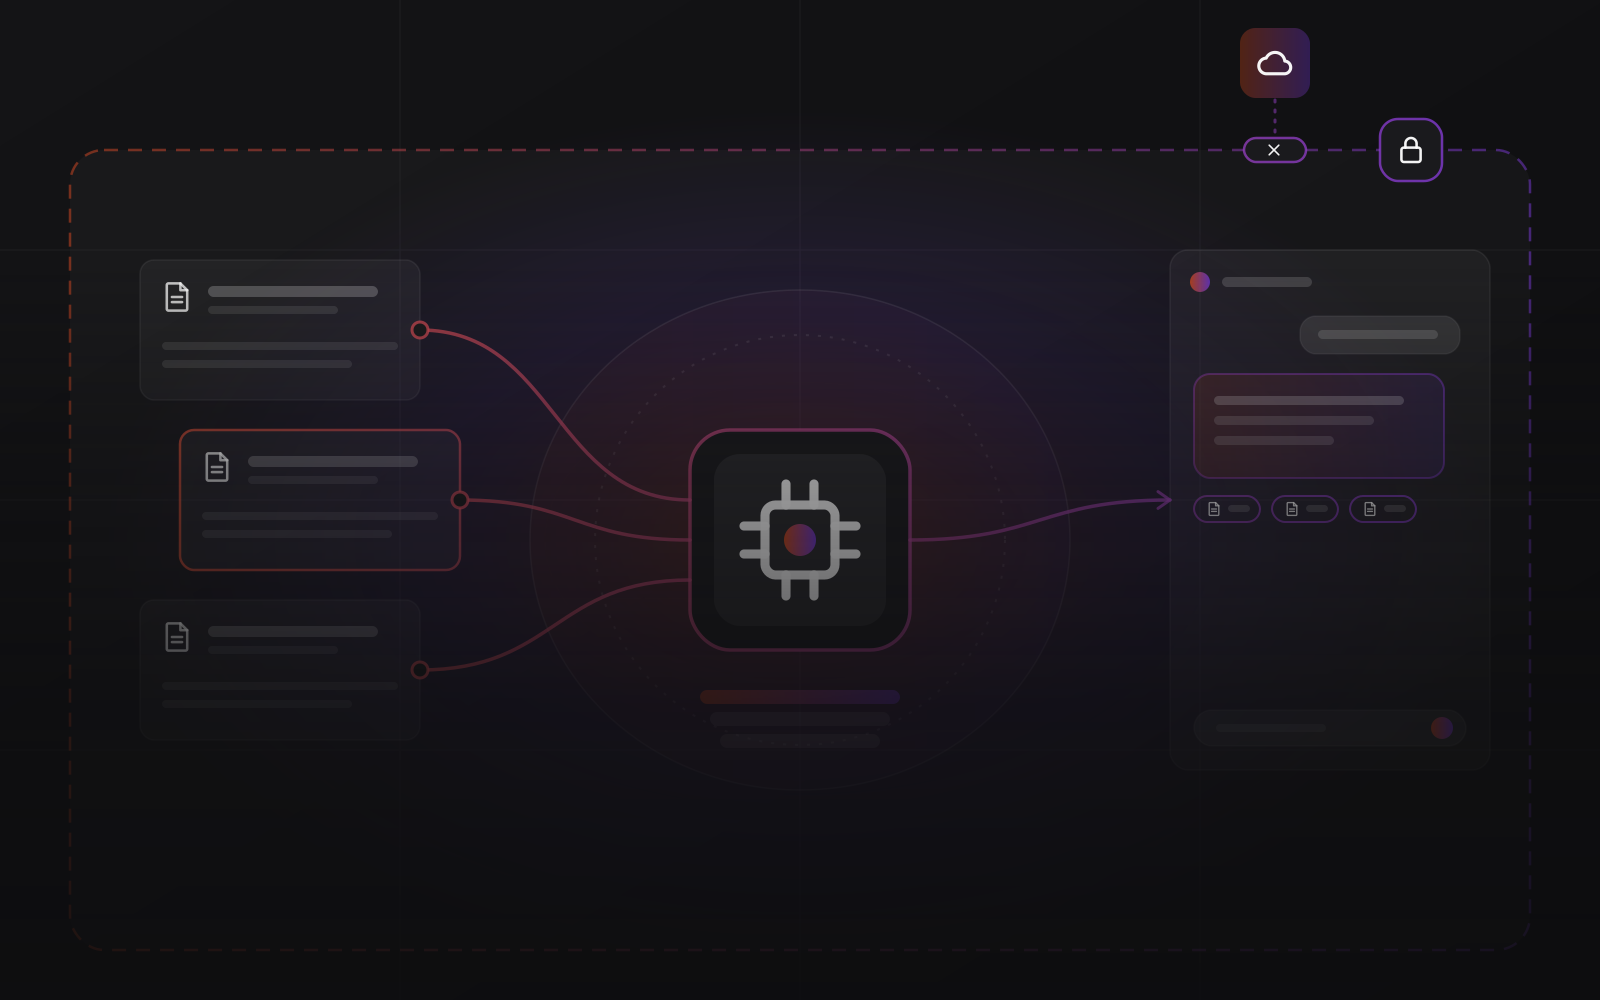
AI integration services for businesses that cannot send contracts, client lists or ledgers to a public API. We connect open models on your own hardware, or a provider you choose, to your documents, CRM and ERP. Then we host and support the result.
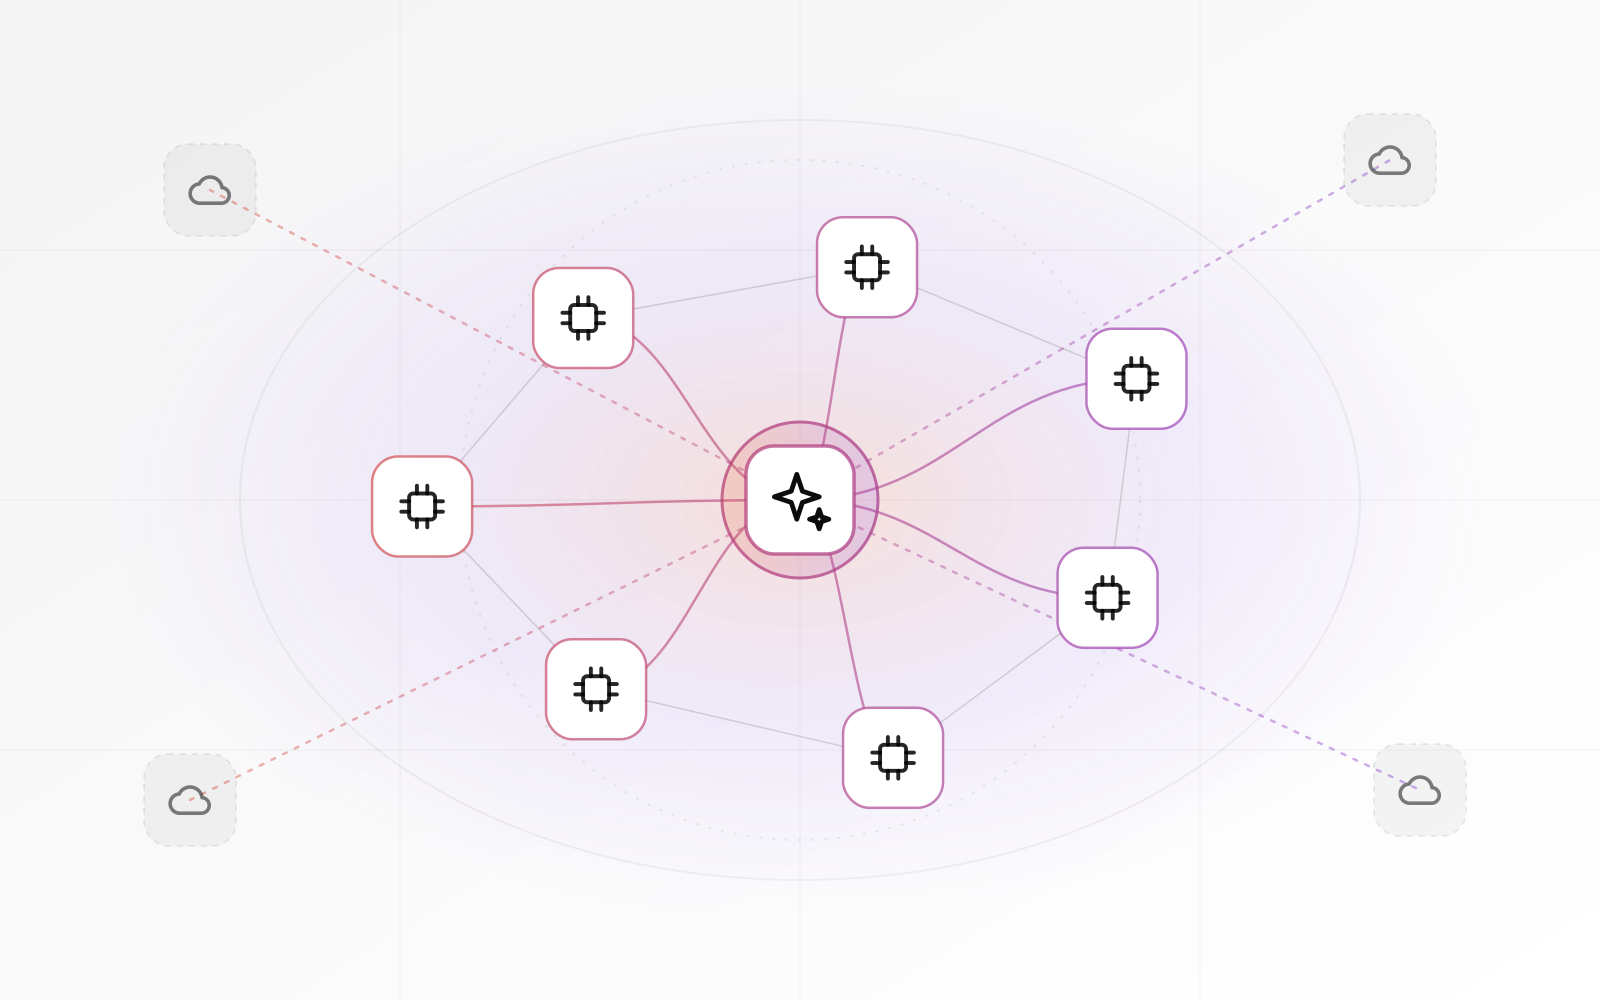
Models run on your hardware or a private server, so prompts and documents stay on your network.
Answers come from your own documents, with the source shown.
Local models carry no usage fee. Hosted models, if you pick one, bill through their provider.
Local AI, properly
Cloud AI is rented intelligence on someone else's terms. Local AI is a capability you own: sized to your needs, grounded in your knowledge and run by the team that built your systems.
AI in detail
AI integration means connecting a language model to the systems where your work already happens. The model reads your documents, tickets and records, answers in plain language and drafts the routine work. People approve anything that matters.
We work in three steps. First, we pick the workflows where AI saves real hours, such as answering from contracts or drafting replies. Second, we connect the model to your data with RAG and test it on questions your team wrote. Third, we deploy it where people work: your CRM, ERP, inbox or a chat page.
The honest part: a local model will not out-trivia the largest cloud models, and it does not need to. It wins when the answer lives in your own data. When a hosted model is the better tool for one task, we say so. Many setups are hybrid. For wider workflow projects, see custom AI automation.
Where engagements start
Legal, medical, financial or simply confidential: teams that want AI but cannot ship documents to a public API.
Assistants that know the internet but not your products, prices or processes.
An experiment stuck for a year because nobody owns the data pipeline, the tests or the hosting.
Services
From a single assistant to a full private stack.
Open models served from your GPU or private server, sized and monitored.
Answers grounded in your real files, with sources your team can check.
Site and chat assistants that answer, qualify and book, in your voice.
Extraction, classification and drafting across invoices, contracts and mail.
Ask your business systems questions in plain language.
Multi-step workflows with retries, guardrails and human approval.
Hardware
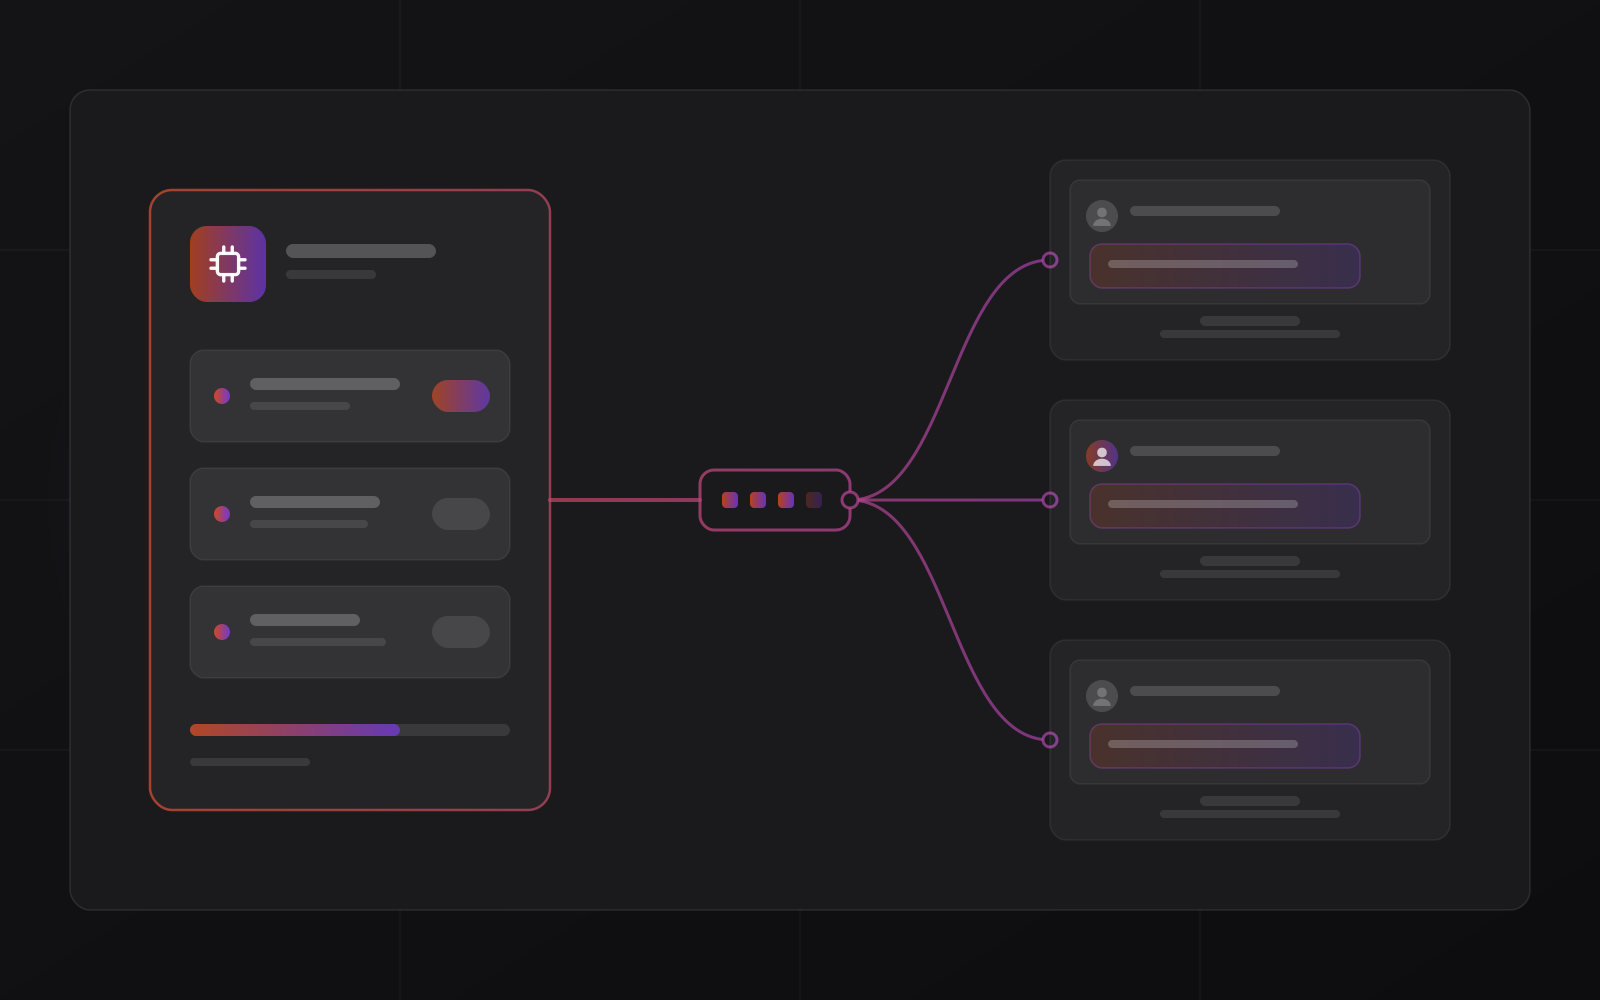
A workstation GPU can serve a quantised open model to a small team. Larger models need more memory, so we size the machine to your workload before you buy. We build and harden the server, or deploy on a private one.
Integration
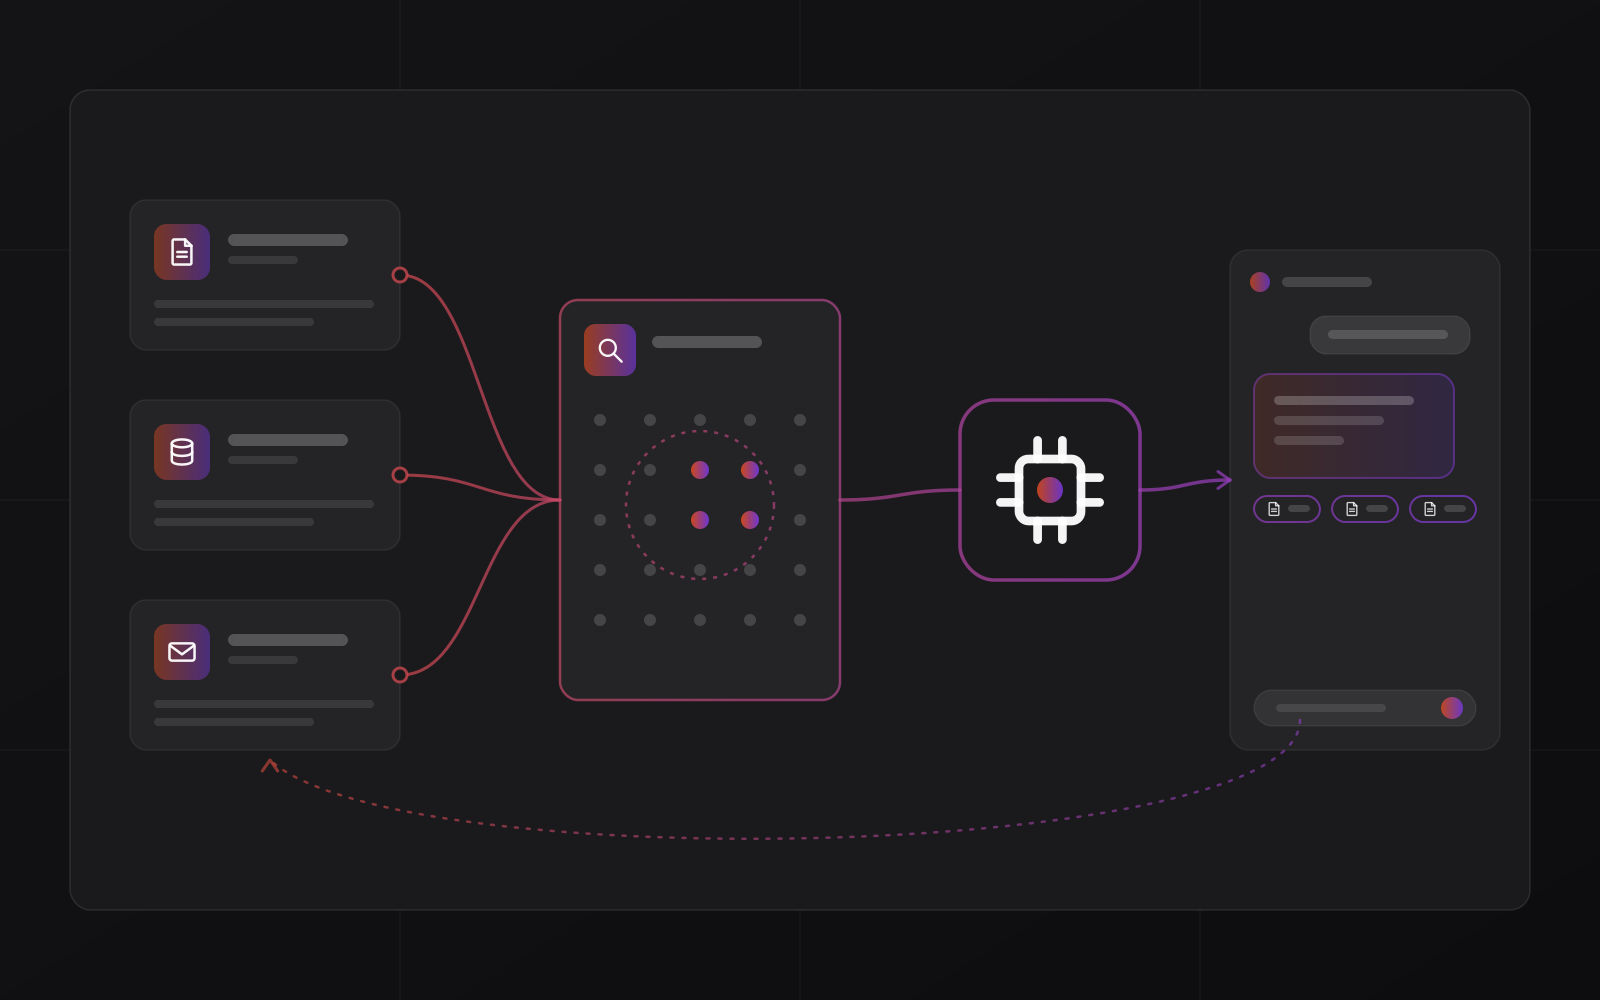
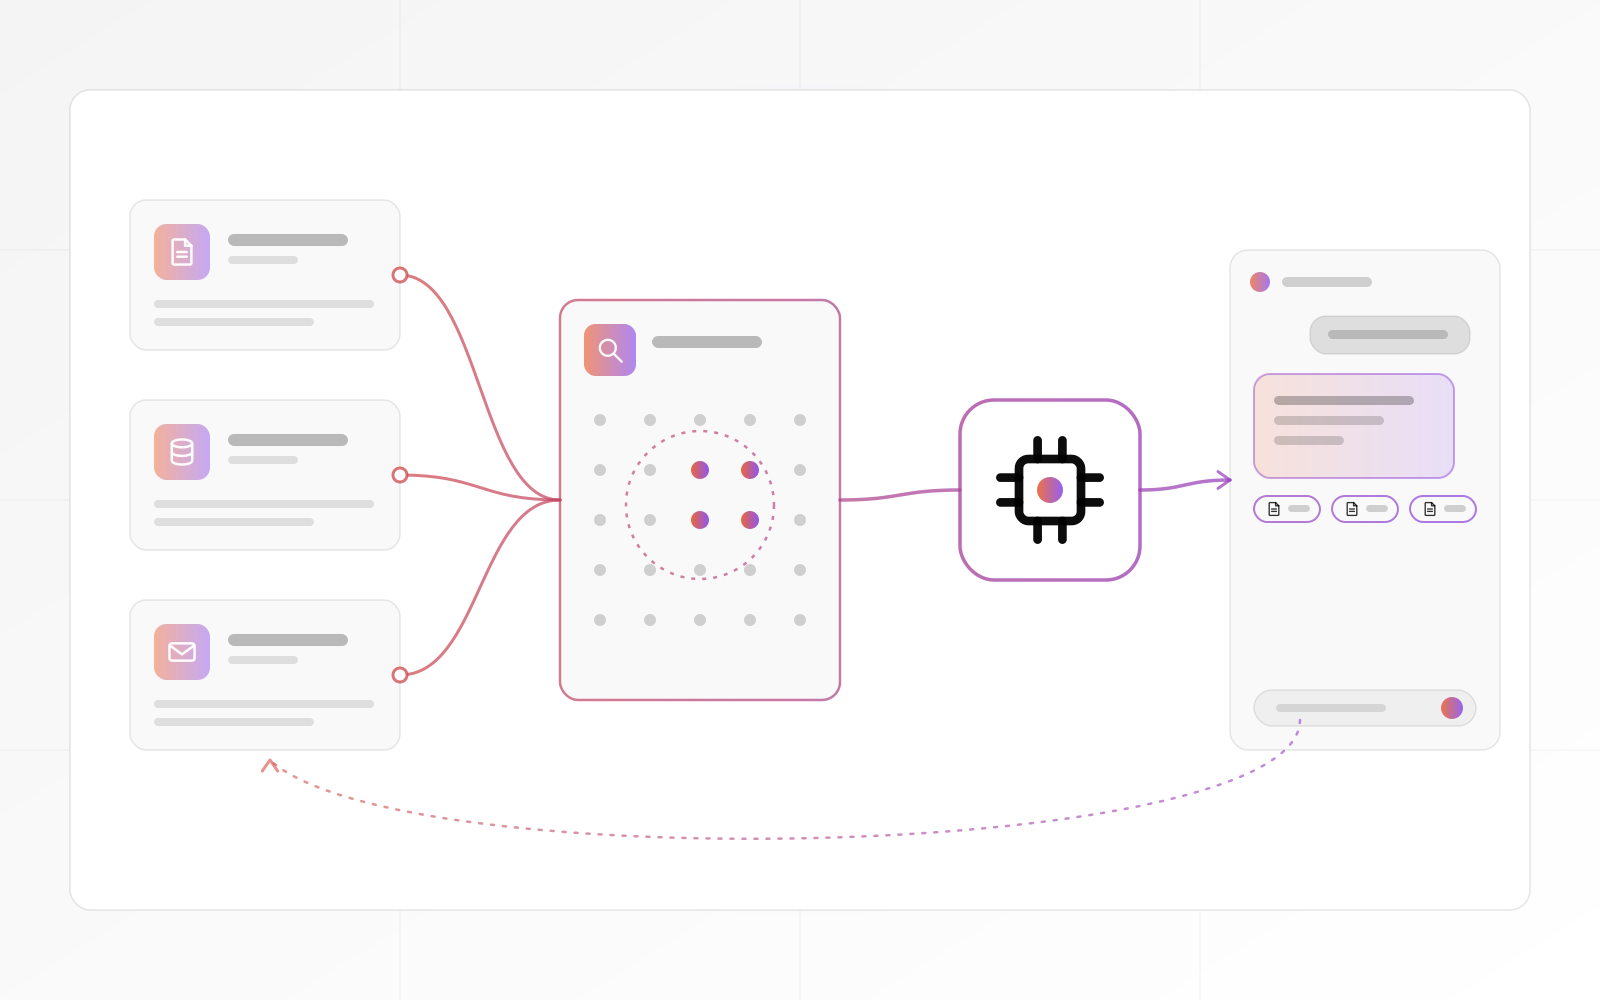
The assistant lives inside your CRM, ERP and inbox. It drafts replies, summarises threads and answers questions against live records. Where the stakes are real, a person approves the action.
Delivery
Every stage runs on your infrastructure, and you can stop at any stage that already solves the problem.
Pick the workflows where AI pays, ranked by hours saved.
Clean and structure documents, chats and records for retrieval.
Set up RAG first. Fine-tune only where it measurably helps.
Score the assistant on a test set your team helped write.
Serve it from your GPU or private server, with roles and logging.
Watch quality and speed, and keep the audit log on your server.
Handover
Every quote lists these items line by line, with a timeline and a payment schedule.
Already shipping
We build AI into our own software first. Each product lets you choose the provider, including models on your own server.
Compare
What changes when the model runs on your side of the network.
| What matters | Local AI | Cloud AI API | AI SaaS tool |
|---|---|---|---|
| Where your data goes | Stays on your network | Sent to the provider | Held in the vendor's cloud |
| Usage fees | None for local models | Per token | Per seat or per use |
| Tuned on your documents | RAG and fine-tuning | RAG, some fine-tuning | Limited |
| Works without internet | Yes, on your LAN | No | No |
| Best when | Data is confidential | You need the largest models | You want a ready tool |
AI that shipped.
Words from clients, as they wrote them:
"MrZaKaRiA programming services are exceptional. They’ve helped us develop robust ERP solution that have streamlined our operations. Their team is knowledgeable, efficient, and a pleasure to work with."
"As a startup, we needed a reliable partner for our online presence. The web design, programming, and hosting services we received were outstanding. MrZaKaRiA played a crucial role in our success. We couldn’t be happier!"
FAQ
What owners ask before bringing AI in-house.
They connect a language model to your own systems and documents, so it can answer questions, draft work and automate routine steps. The scope covers choosing the model, preparing your data, building retrieval, testing quality and deploying where your team works.
Privacy, cost and fit. Your contracts and client lists stay on your network, a local model has no per-token fee, and a model grounded in your documents answers like someone who works there. A cloud API is still the better tool for some tasks, and we say when.
It depends on the model size and how many people use it. A workstation GPU can serve a quantised open model to a small team. Larger models and more users need more GPU memory or a dedicated server. We size it from your workload before you buy.
Scope drives cost. Custom AI projects start at $10,000, scoped up front with a fixed price and milestones. The quote is itemised and keeps our work separate from any hardware or provider fees. We scope it, quote it and start within 3 to 5 business days.
The team that built it, if you want. Models, prompts and data pipelines are monitored, and every prompt is logged on your server. Or we hand it to your team with documentation.
Start
One working session: where AI pays in your business, what stays local, what it costs to run and what a first pilot involves.